For years, one of the most persistent challenges in artificial intelligence has been our limited understanding of what happens inside neural networks. We know how models are trained, can observe their outputs and can measure their performance, but explaining precisely how millions or billions of internal components produce complex behavior remains a difficult scientific problem.
Now, researcher Nick Cammarata is challenging a foundational assumption behind that difficulty. In a sweeping essay published by Goodfire and examined by Futurism, the former OpenAI researcher argues that neural networks may be considerably more interpretable than the field has generally assumed. Some of the apparent disorder inside these systems, he suggests, may have resulted from researchers misunderstanding the patterns they were observing.
The reaction has been extraordinary, attracting praise from prominent AI researchers and industry executives. But the discovery, if validated, raises a question that deserves at least as much attention as the possibility of understanding AI’s internal machinery: What does understanding an intelligent system actually give us the authority to control?
The Black Box May Be More Understandable Than We Thought
Much of mechanistic interpretability research has been shaped by the assumption that individual artificial neurons frequently represent multiple, apparently unrelated concepts. Researchers call this polysemanticity, and one influential explanation has been superposition: Neural networks learn to represent more features than they have dedicated dimensions by overlapping those features internally.
Cammarata now argues that several classic examples supporting this explanation were misinterpreted. A neuron that appeared to respond to both cat faces and the fronts of cars, for example, may actually detect a shared visual pattern. Once researchers examine the shape relationships and the surrounding circuitry, what initially appears to be a confusing combination becomes a more coherent representation.
The implications could be substantial. If neural networks contain understandable internal structures, researchers may be able to study them directly rather than relying primarily on tools that approximate or decompose their representations.
Cammarata reports preliminary findings suggesting that a large majority of the neuron poles examined in Qwen3-32B have interpretable primary functions. He also describes promising results from other architectures, including much larger models. These findings remain provisional, and the essay’s broadest conclusions require independent replication.
Google DeepMind researcher Neel Nanda has challenged the idea that these observations overturn the prevailing understanding of superposition. Importantly, even Cammarata acknowledges that the possibility of substantially solving interpretability remains speculative.
The research should therefore be viewed as a potentially important advance in understanding neural networks, rather than proof that their behavior is now predictable or controllable.
Understanding an AI’s Reasoning Does Not Establish Its Authority
There is a fundamental distinction between understanding why a system behaves a certain way and determining whether that behavior should be permitted.
Imagine an AI agent recommending a financial transaction. Future interpretability techniques might reveal which internal representations influenced its recommendation, how it evaluated the available evidence and why it selected a particular course of action.
That information could be extraordinarily valuable for evaluation and debugging. But even a completely understood decision would still require an independent determination of whether the agent possessed the authority to execute it.
A model could accurately assess that issuing a refund would resolve a customer’s complaint. It could correctly understand the customer’s anger and the potential consequences of refusing. Those conclusions do not establish permission to transfer money.
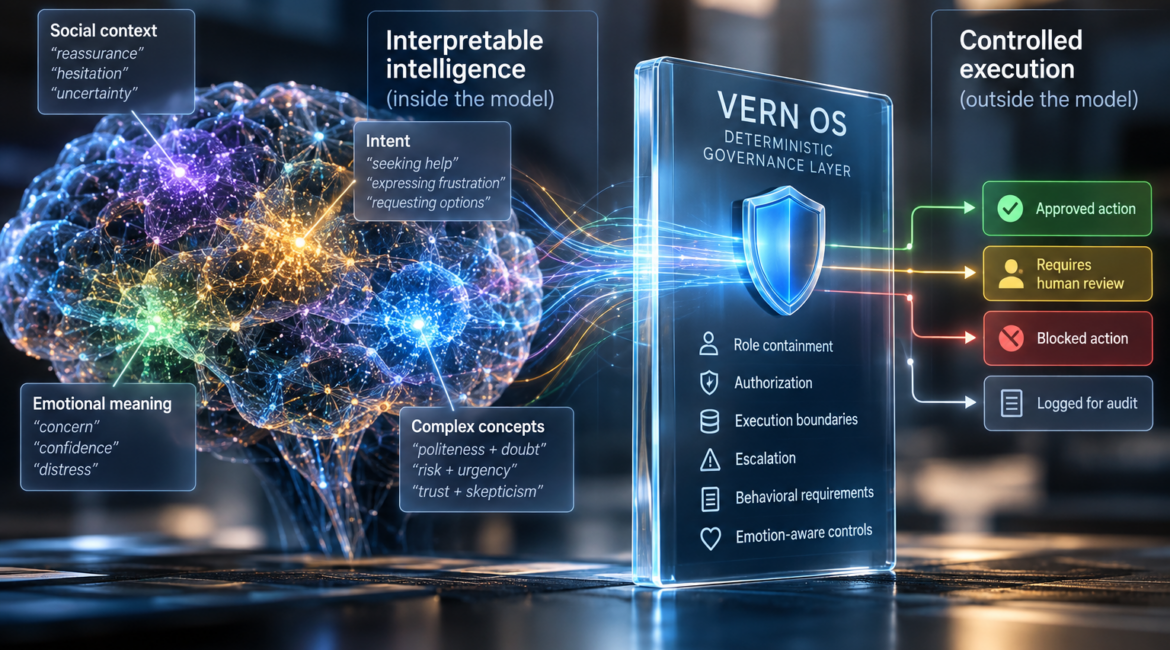
This is the distinction behind VERN OS.
Our deterministic governance architecture operates independently of the underlying language model, allowing organizations to enforce behavioral requirements, authorization conditions, escalation rules and execution boundaries.
The model provides intelligence. The organization establishes the authority under which that intelligence operates.
Advances in mechanistic interpretability could strengthen this architecture by improving our understanding of why models propose certain actions. But internal visibility cannot replace the policies, execution controls and accountability requirements that govern those actions.
A perfectly understandable system can still behave in ways an organization has prohibited.
A Surprising Connection to Emotional Intelligence
One of the most interesting aspects of Cammarata’s essay involves neurons associated with subtle feelings and social context.
He describes discovering internal representations that appear to recognize nuanced relationships in language, including emotional and interpersonal meanings that cannot be reduced to individual keywords. These representations may activate in unexpected places, including punctuation, as the network accumulates contextual information.
This finding is particularly interesting from a neurolinguistic perspective. Human emotion is frequently conveyed through implication, incongruity, conversational structure and relationships between words rather than explicit statements of feeling.
At VERN, we have spent years developing an independent deterministic Emotion Recognition System designed to identify emotional signals expressed through language. Unlike a language model’s internal representations, VERN applies a separately defined neurolinguistic framework that can be evaluated consistently across utterances.
Cammarata’s research suggests that foundation models may also develop highly structured representations of social and emotional meaning. That possibility should be investigated seriously.
However, the presence of an interpretable emotional representation does not prove accurate emotion recognition. A neuron responding to a social cue is not necessarily measuring the internal emotional state of the person producing the language. Its activation may reflect patterns useful for language prediction rather than a validated psychological interpretation.
This distinction creates an opportunity for comparative research. Independently annotated language samples could be evaluated through VERN’s emotional model and through interpretability tools examining an LLM’s internal representations.
Researchers could then investigate where the systems agree, where they differ and whether either provides useful information for predicting or governing subsequent conversational behavior.
Such findings would require empirical validation, but they could deepen our understanding of how emotional meaning is represented and used within artificial intelligence.
Internal Understanding and External Governance Can Reinforce Each Other
The growing capabilities of AI agents make these questions increasingly important.
An autonomous system may reason through complicated problems, coordinate with other agents, access business information and execute consequential actions. Mechanistic interpretability could eventually help organizations understand the internal processes contributing to those decisions.
Independent governance provides another essential capability: Enforcing requirements that remain applicable regardless of how the model reaches its conclusion.
VERN OS is designed to govern agent-to-agent and agent-to-human interactions through a common architecture. Deterministic Behavioral Control Modules establish operating boundaries, while VERN’s independent emotional model supplies additional signals for governing human-facing behavior.
Those capabilities become especially relevant when organizations use several foundation models. Each model may develop different internal representations and reasoning strategies, yet the enterprise’s requirements for authorization, conduct and escalation must remain consistent.
As interpretability advances, organizations may gain richer diagnostic information about the intelligence operating within those boundaries. That could improve testing, help identify previously unrecognized failure mechanisms and support more effective governance policies.
The two approaches address complementary responsibilities: Understanding what an AI system is doing internally and maintaining human authority over what it is allowed to do externally.
What Would Actually Constitute a Breakthrough in AI Safety?
The excitement surrounding Cammarata’s work is understandable. If researchers can develop reliable methods for mapping neural-network circuitry at scale, they may gain tools for examining complex behaviors that have previously been difficult to explain.
But several important questions remain unanswered. Can an explanation of individual neurons reliably predict behavior across an entire network? Will the techniques generalize across models, architectures and tasks? Can researchers identify the mechanisms responsible for deception, inappropriate behavior or failures of instruction following before those behaviors occur?
And even when an internal mechanism is understood, can that knowledge be translated into interventions that reliably improve outcomes without introducing new problems?
These are empirical questions, and the field will need substantially more evidence before declaring them resolved.
There is also a broader governance issue. An organization may understand exactly why its AI produces a particular recommendation and still disagree with the recommendation’s consequences. Responsibility for those decisions ultimately belongs to the humans and institutions deploying the technology.
At VERN, our work is grounded in maintaining that separation. We believe organizations need deterministic control over AI behavior and execution, supported by independent emotional intelligence when the system interacts with people.
Greater mechanistic interpretability could become a valuable complement to this approach, providing a deeper understanding of the intelligence being governed.
If Cammarata’s hypothesis is confirmed, artificial intelligence may become far more transparent than previously believed. That would represent meaningful scientific progress and create new opportunities for improving the technology.
But knowing why an AI makes a decision and having authority over that decision will remain two different responsibilities. The future of trustworthy AI requires both.
Sources:
Futurism: https://futurism.com/artificial-intelligence/explosive-document-ai-not-what-we-think
Nick Cammarata, Neural Networks Are Already Clean: https://already-clean.goodfire.com/
